How Banks Can Deduplicate Historical Customer Data and Keep Matching In-House in 2026

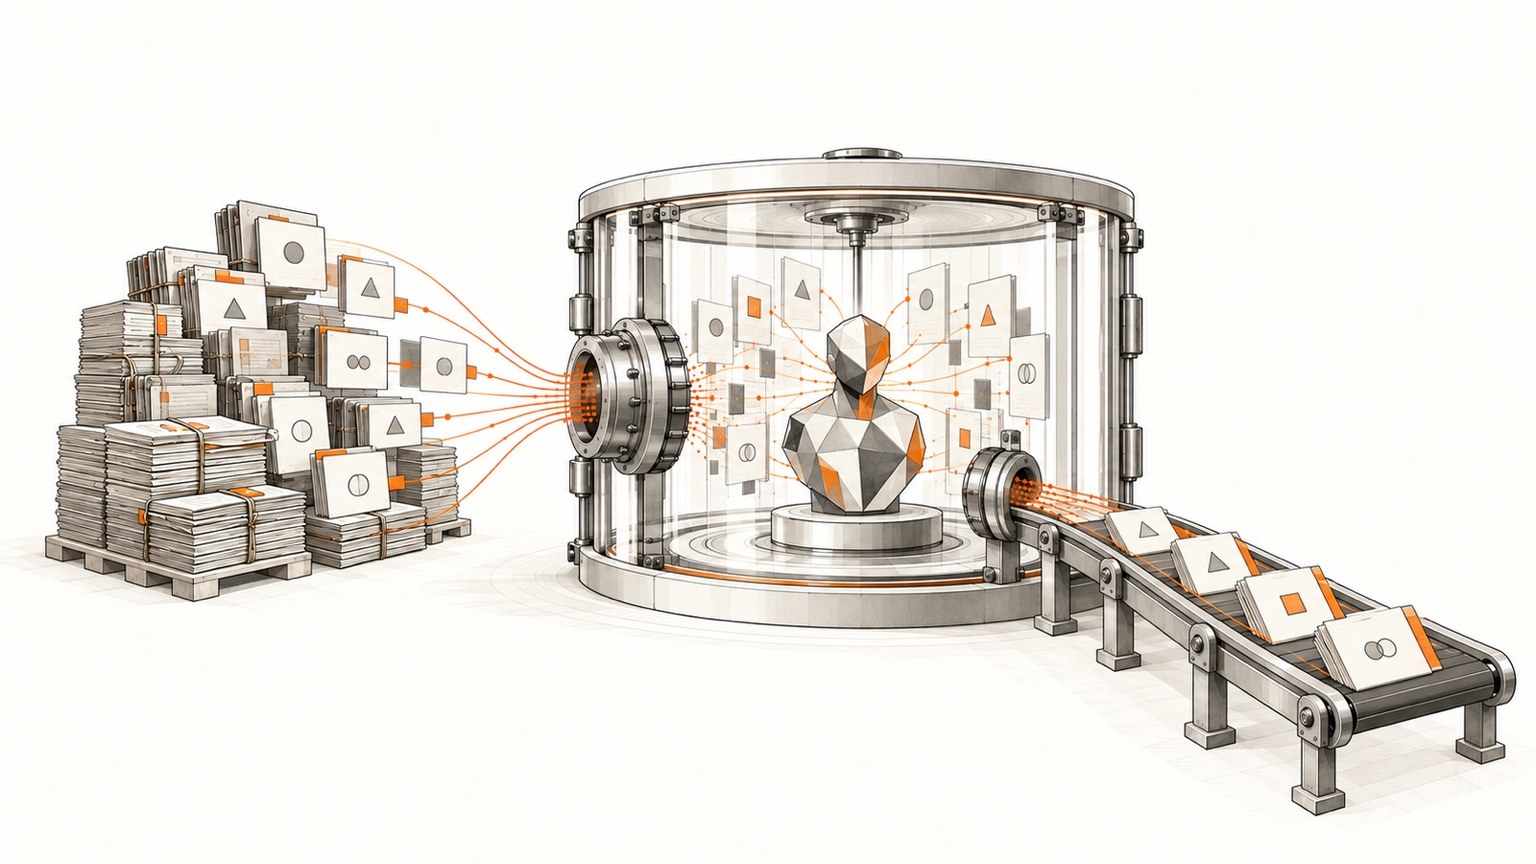
TL;DR: A bank can deduplicate historical customer data once, then keep matching current inside its own perimeter. Preserve source records and lineage, tune deterministic, fuzzy and probabilistic methods against labelled truth, reconcile before cutover, and feed new or changed records through the same governed GraphQL resolution layer.
Test the migration path on your own data. Book a Demo · Try Tilores Studio (Free).
On this page
- What architecture keeps matching in-house?
- What are the seven migration steps?
- How should matching methods be combined?
- How should the bank reconcile and cut over?
- How does ongoing matching work after migration?
- Which banking controls belong in the design?
- What evidence should the programme retain?
- Frequently asked questions
A historical deduplication project should leave a bank with a continuing identity capability, not a cleaner database that immediately starts accumulating duplicates again. The practical design separates three concerns: source systems keep their operational roles, an entity resolution layer decides which records belong together, and the bank retains ownership of mastering, risk decisions and steward review.
This matters during a core-platform migration, acquisition or customer-data consolidation. The backfile is finite, but identity is not. Addresses change, names vary, accounts move and new channels keep creating records. The migration therefore has to establish the same matching rules, lineage and review boundaries that will operate after cutover.
What architecture lets a bank deduplicate history without outsourcing its operating model?
The bank should place entity resolution beside its existing core, MDM, customer platform, warehouse and KYC systems. The resolution layer normalises incoming records, compares them, links related records and returns a resolved entity. It does not need to become the system that owns accounts, product servicing, regulatory cases or the bank’s governance model.
Tilores resolves records at ingestion and serves the resulting entity graph through GraphQL. The bank can keep its existing golden-record policy and decide which values, if any, are written back to an authoritative master. Original source records and provenance remain available, so a unified view does not erase the evidence used to assemble it.
| Layer | Primary responsibility | What remains bank-owned |
|---|---|---|
| Source systems | Create and update customer, account and interaction records | Operational data, source identifiers and access policy |
| Entity resolution | Normalise, compare, link, split and assemble records | Approved configuration, thresholds and deployment perimeter |
| Golden-record or MDM layer | Apply survivorship and publish mastered values | Authoritative-value policy and downstream contracts |
| Risk and compliance systems | Run KYC, sanctions, PEP, adverse-media and fraud workflows | Risk appetite, alert disposition and case decisions |
| Data stewardship | Review uncertain or consequential links | Decision rights, evidence and escalation |
Keeping matching in-house can mean deploying inside the bank’s AWS account, another cloud environment, its data centre or an air-gapped network. The Tilores deployment options keep the matching rules and GraphQL API consistent while allowing the data perimeter to follow the bank’s architecture and residency requirements.
What are the seven steps for historical deduplication and ongoing matching?
- Define the customer decision and its owner. Name the decision the resolved identity will support. Examples include migration reconciliation, onboarding duplicate checks, customer service, credit exposure aggregation or AML investigation. Assign owners for match policy, steward review, privacy, model validation and downstream acceptance.
- Contract each source before moving data. Record the source system, stable record identifier, field meanings, update semantics, deletion behaviour and lineage requirements. A migration extract without this contract becomes a pile of values that cannot be reconciled reliably after matching.
- Normalise fields while retaining originals. Standardise values used for comparison, such as name casing, telephone formats and parsed addresses. Keep the original values alongside the normalised representation. This gives matching comparable inputs without rewriting the historical evidence.
- Build labelled truth from difficult cases. Create confirmed matches and confirmed non-matches from the bank’s real data. Include common names, shared addresses, transliteration, missing identifiers, household relationships, business customers and records that look similar but belong to different people. Split the labels into tuning and holdout sets.
- Resolve the historical backfile as a controlled run. Load the agreed sources, freeze the configuration version and process the full historical scope. Capture record counts, entity counts, links, splits, rule hits, review cases and rejected records. Do not overwrite source systems during this run.
- Reconcile before changing downstream decisions. Compare the proposed entity state with source totals, the previous customer view and the labelled holdout set. Investigate unexplained count changes, high-impact merges, source omissions and steward backlog. Approve cutover only when the bank can explain the differences.
- Continue matching new and changed records. After cutover, send each new or changed source record through the same GraphQL resolution layer. Monitor accuracy, freshness, lineage, review volume and deletion handling. Treat configuration changes as controlled releases, with historical reprocessing scoped and reconciled separately.
Our entity resolution rollout covers preparation, labelled truth, deployment, parallel comparison and governed operations as parts of matching. The algorithm alone cannot provide a safe cutover.
New posts on entity resolution, identity data and AI. No spam, unsubscribe any time.
How should a bank combine deterministic, fuzzy and probabilistic matching?
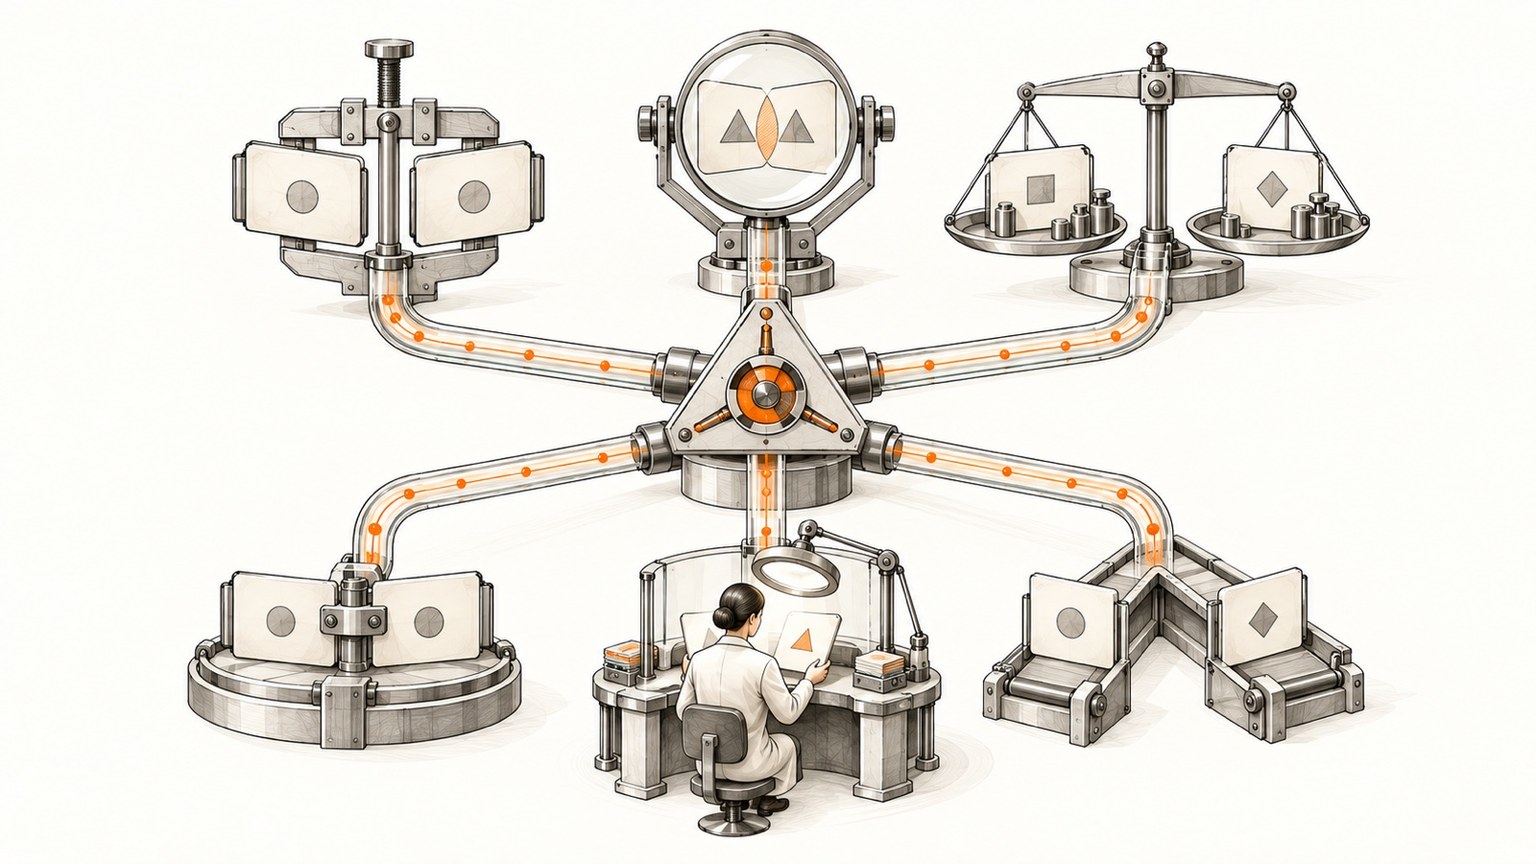
Use the three methods distinctly. Deterministic matching applies exact rules to trusted identifiers or tightly controlled combinations. Fuzzy matching measures similarity between non-identical values, such as spelling variants. Probabilistic matching combines agreements, disagreements and the relative rarity of signals into a score or likelihood.
The methods complement one another, but they answer different questions. An exact match on a verified identifier carries a different meaning from a close name comparison. A probabilistic model can then weigh several weaker fields together. The US Census Bureau’s review of modern record-linkage methods traces this discipline back to the Fellegi-Sunter framework and explains why entity-level partitioning matters beyond isolated record pairs.
Turn scores into three governed outcomes:
- Automatic link: evidence is strong enough for the approved use case.
- Steward review: evidence is ambiguous or the consequence of a wrong link is high.
- No link: evidence does not clear the configured boundary.
There is no universal threshold. A migration team should measure precision and recall against labelled bank data, then set boundaries for each decision. A false merge can expose one customer’s information inside another customer’s workflow, so precision is also a privacy control. A false non-match leaves duplicates in place and can fragment exposure, service and due-diligence views.
How should a bank reconcile and cut over the resolved customer view?
Run the proposed entity view in parallel with the current process. Reconciliation should explain changes rather than merely confirm that a job completed. At minimum, compare source-record totals, resolved-entity totals, links created or removed, records rejected, unresolved records and cases routed to review.
The cutover gate should also test downstream behaviour:
- Can each source record be traced to its current entity?
- Can a consumer retrieve only the fields it is authorised to use?
- Do corrections, splits and deletions reach every contracted consumer?
- Can a steward see the evidence that produced a match?
- Can the bank restore the previous configuration and entity state?
Keep source mutation outside the first resolution pass. Once the reconciliation report is accepted, the bank can publish identifiers or mastered values through its existing integration controls. This preserves a clear rollback boundary and prevents a matching experiment from becoming an irreversible data rewrite.
How does ongoing matching stay in-house after the migration?
The historical run and the live path should share one configuration, one source contract and one ownership model. New and changed records enter the resolution layer through GraphQL. Tilores normalises the submitted fields, applies deterministic, fuzzy and probabilistic matching, then creates, updates, merges or splits the resolved entity as the evidence requires.
Applications query the current entity rather than rebuilding identity inside each request. The core system still owns the account. The MDM layer still owns survivorship. Compliance still owns case decisions. The resolution layer owns the narrower job of maintaining which records belong to the same person or organisation.
Rule changes need release discipline. Test the candidate configuration on frozen truth, observe its effect on a representative shadow stream, approve the changed link distribution and then deploy it. We apply new rules to new data; changing historical outcomes requires a separate re-ingestion operation. That boundary keeps routine live matching from silently rewriting the migration baseline.
Which regulatory and operational controls belong in the design?
Entity resolution is infrastructure, but its controls need to fit the bank’s obligations. The Basel Committee’s risk data principles emphasise governance, data architecture, accuracy, integrity, completeness, timeliness and reconciliation. Those ideas translate directly into source contracts, automated lineage, validation and monitored exception handling.
For personal data, GDPR Article 5 requires purpose limitation, data minimisation, accuracy, storage limitation, integrity, confidentiality and accountability. The matching design should therefore limit fields to the approved purpose, preserve correction and deletion paths, and record enough evidence to explain consequential links.
The current FATF Recommendations, last amended in June 2026, state in Recommendation 10 that jurisdictions should require financial institutions to identify and verify customers and conduct ongoing due diligence. A resolved customer view can provide better identity context to sanctions, PEP and adverse-media screening, but it should not decide those cases. Screening thresholds, risk classification and human disposition remain separate controls.
That distinction also reduces false alerts. OpenSanctions’ matching guidance recommends tuning filters and thresholds for the use case and maintaining human review. The resolved identity should improve the inputs available to a screening process, while the screening process retains its own evidence and decision record.
What evidence should the migration programme retain?
| Evidence | Question it answers | Acceptance owner |
|---|---|---|
| Source contract | Which records, fields and updates are in scope? | Data owner |
| Labelled truth set | What does a correct match or non-match look like? | Business and model validation |
| Configuration version | Which normalisation and matching behaviour ran? | Resolution owner |
| Reconciliation report | Can every material difference be explained? | Migration lead |
| Steward queue report | Can ambiguous cases be reviewed within the operating capacity? | Operations owner |
| Access and deletion tests | Do privacy controls work through every downstream path? | Privacy and security |
| Rollback exercise | Can the bank restore the previous known state? | Technology risk |
The strongest design produces this evidence as part of normal operation. That makes the historical migration auditable and gives the ongoing matching service a measurable operating baseline.
Frequently asked questions
Can a bank deduplicate customer data without replacing its core systems?
Yes. Tilores can sit beside core banking, MDM, customer, warehouse and compliance systems as the matching and linking layer. Those systems keep their existing responsibilities while consuming a resolved entity through GraphQL.
Does the entity resolution platform have to own the golden record?
No. The bank can retain golden-record ownership in its existing MDM or mastering process. Tilores maintains the resolved entity graph and provenance, while the bank controls survivorship, authoritative values and downstream publication.
How does a bank move from batch deduplication to ongoing matching?
The bank uses the approved migration configuration for the live ingestion path, then submits new and changed source records through GraphQL. Historical reprocessing remains a separate, reconciled operation whenever a rule change needs to affect older records.
How can a bank reduce false customer merges?
A bank reduces false merges by testing deterministic, fuzzy and probabilistic methods against labelled truth, measuring precision separately from recall, routing ambiguous cases to stewards and using stricter boundaries where a wrong link could expose data or change a risk decision.
Can sanctions, PEP and adverse-media screening use the resolved customer view?
Yes. Those systems can use the resolved customer view as better identity context, while retaining separate screening logic, thresholds, evidence and human case decisions. Entity resolution improves who is being screened; it does not replace the screening control.
How can a bank test this architecture before cutover?
Start with a controlled extract, a labelled set of difficult customer pairs and a deployment perimeter that reflects the intended production model. Validate match behaviour and reconciliation before connecting any downstream decision.
Book a Demo or Try Tilores Studio (Free).
Sources
- Entity Resolution Infrastructure, Tilores.
- Deployment Options, Tilores.
- What an Entity Resolution Rollout Actually Looks Like in 2026, End to End, Tilores.
- How to Change Entity Resolution Rules Without Breaking Production, Tilores.
- Risk Data Aggregation and Risk Reporting, Basel Committee on Banking Supervision.
- Regulation (EU) 2016/679, Article 5, EUR-Lex.
- The FATF Recommendations (last amended June 2026), Financial Action Task Force.
- A Review of Modern Multinomial-Derived and Partition-Based Record-Linkage Methods, US Census Bureau.
- The Matching API, OpenSanctions.
See what resolved entity data does for your business — and your AI.