Can You Buy a Matching Engine and Keep Your Golden Record in 2026?

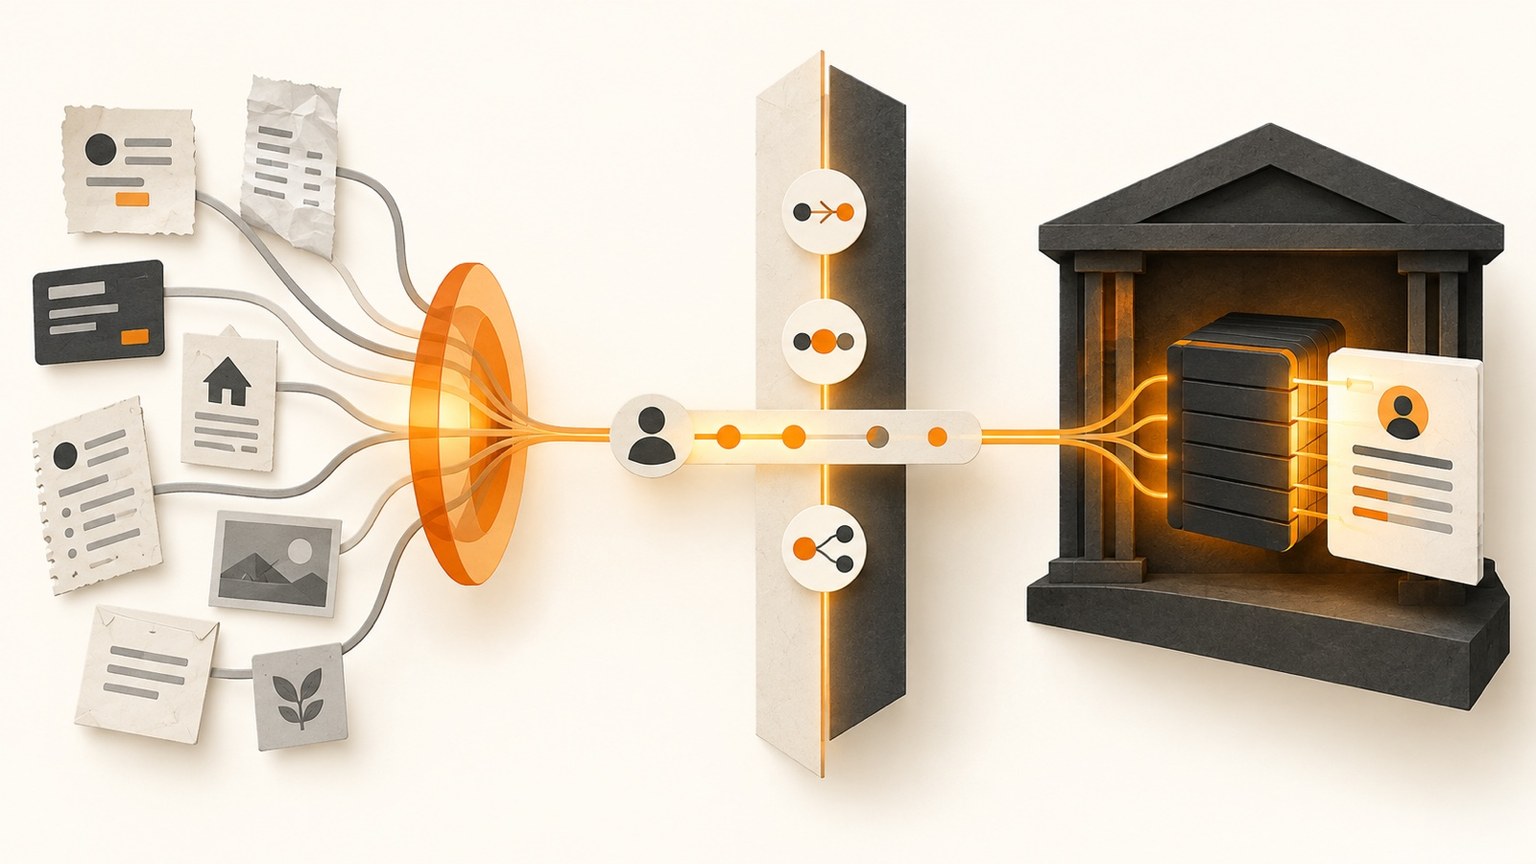
TL;DR: Yes. A bank can use a dedicated entity resolution engine to normalise records, identify which records belong to the same customer and maintain the identity graph, while its own mastering layer chooses surviving values, controls approvals and publishes the golden record to downstream systems.
Test this architecture on your own data. Book a Demo · Try Tilores Studio (Free).
On this page
- What does buying only the matching engine mean?
- Where should matching stop and mastering begin?
- How should data move between the two layers?
- Which contract prevents the layers from drifting?
- When does this architecture fit?
- What does bank compliance require?
- How should a bank evaluate the architecture?
- What belongs in the procurement requirements?
- Frequently asked questions
What does buying only the matching engine mean?
Buying the matching engine means separating two jobs that often arrive in one large master data management programme. Entity resolution decides which source records represent the same person or organisation. Mastering decides which values become authoritative, who can approve a change and where the finished customer profile is published.
The boundary matters. A bank should specify more than a stateless similarity function: normalisation, candidate discovery, distinct deterministic, fuzzy and probabilistic approaches, evidence for identity decisions, and identity change handling. It can then keep field survivorship, business approvals and golden-record publication in systems it already owns.
This is the focused architecture described in our guide to entity resolution alongside master data management. It lets a bank add a specialist identity layer without replacing its customer master, data platform or operating model.
Where should matching stop and golden-record mastering begin?
The matching layer should own identity evidence. The mastering layer should own the bank’s business definition of the customer record. The table shows the recommended ownership for this architecture.
| Responsibility | Matching engine | Bank-owned mastering layer |
|---|---|---|
| Source-data preparation | Specify normalisation of names, addresses, phone numbers, email addresses, dates and company attributes, with original-value retention where required | Set source ownership, data-quality obligations and permitted uses |
| Candidate discovery | Find records that are plausible matches without comparing every record with every other record | Supply eligible source populations and access controls |
| Identity decision | Meet the bank’s requirements for distinct deterministic, fuzzy and probabilistic methods, match rules and entity-level consistency checks | Approve policy, risk bands and review authority |
| Identity graph | Meet the bank’s requirements for records, links, stable entity identifiers, merge history and split history | Reference the resolved entity identifier in mastered outputs |
| Golden-record values | Provide survivorship and golden-record shaping when required | Choose the final field values when mastering remains in-house |
| Human workflow | Provide evidence for uncertain links and support reversible decisions | Own queues, approvals, segregation of duties and escalation |
| Publication | Emit current identity and change events | Publish the mastered record to core banking, CRM, KYC, analytics and service systems |
The split is configurable. Tilores can shape a golden record, but the bank does not have to move that responsibility. The useful question is where each decision already has an owner. A bank with established survivorship rules and stewardship should keep them. A bank without those controls still needs to design them, even if it buys the matcher.
How should data move between the matching engine and the master?
A clean integration uses a small number of explicit stages. Each stage has one output and one accountable owner.
- Submit source records. The bank sends permitted customer records and source identifiers to the engine. Its procurement and data contract should state the required normalisation, persistence and original-value-retention behaviour for traceability.
- Find candidates. Search rules identify plausible records. Candidate discovery stays separate from the match decision, so a search hit does not create an identity link.
- Resolve identity. The bank should define the match-rule conditions and the entity-level consistency checks that reject conflicts such as date of birth or tax identifier conflicts.
- Publish identity changes. The entity stream documents CREATE, UPDATE, MERGE, SPLIT and DELETE events, with the affected entity and record identifiers. Event notification is not the same as decision evidence: when a team needs rule evidence, it retrieves the relevant entity edge through GraphQL. Our guide to stable identifiers and downstream change events covers the operating pattern.
- Apply mastering rules. The bank’s layer chooses the surviving address, name, contact details, risk status and other governed attributes. It records who approved an exception.
- Serve the current customer. Operational systems consume the mastered record. Applications that need the live resolved entity can query Tilores through the GraphQL API. The runtime API is GraphQL; the public MCP server supports configuration guidance and query generation, not live customer resolution.
This flow supports bulk history and real-time onboarding with one identity model. It also keeps downstream systems insulated from link churn: a corrected identity decision arrives as a controlled event, and the mastering layer recalculates the affected golden record.
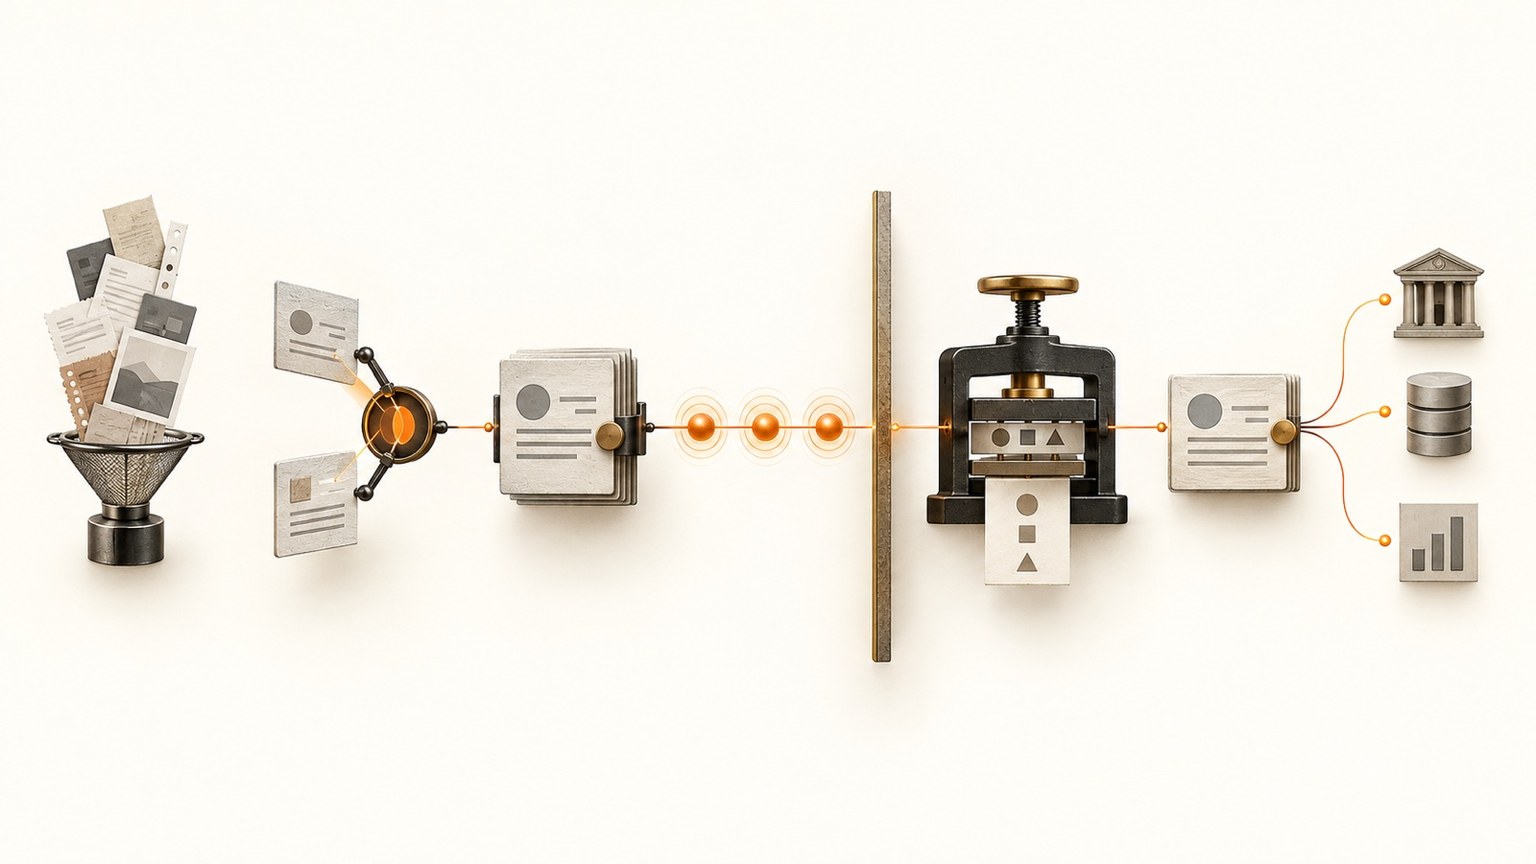
The integration boundary follows the work: resolve and publish identity changes first, then apply bank-owned survivorship and serve the mastered record.
New posts on entity resolution, identity data and AI. No spam, unsubscribe any time.
Which contract prevents the two layers from drifting?
The integration contract is the architecture. A vague handoff such as customer 123 changed is too weak for mastering, audit and recovery. Define these fields before implementation:
| Contract element | What it must establish | Why the master needs it |
|---|---|---|
| Identity key | A stable entity identifier and the source-record identifiers it contains | Prevents downstream references from depending on a preferred source record |
| Event type | CREATE, UPDATE, MERGE, SPLIT or DELETE, with affected entity and record identifiers | Determines which golden records require recalculation |
| Decision evidence | Retrieve the relevant entity edge through GraphQL; record bank-owned review evidence separately | Supports review, challenge and explanation without treating an event notification as proof |
| Handoff version | Bank-owned contract version, event time and processing order | Allows the bank to govern reprocessing of its own mastered output |
| Correction path | A bank-defined process for correcting an identity decision and reprocessing downstream output | Makes a wrong decision operationally manageable |
| Security context | Tenant, purpose, permitted fields and retention obligations | Keeps mastered data within its authorised use |
Upstream data contracts deserve the same attention. A source must declare field meaning, identifier stability, null handling and format changes before records reach matching. These seven entity resolution data-contract rules are a practical starting point.
When is an engine plus bank-owned mastering layer the right choice?
This model fits a bank that already has a customer master, stewardship process or data platform and needs stronger identity decisions inside it. A broader MDM programme fits when the missing capability includes governance, workflow, reference data, domain ownership and distribution across several mastered domains.
| Decision question | Choose a matching engine plus your layer when | Consider a broader MDM programme when |
|---|---|---|
| What already exists? | A customer master and accountable data owners are operating today | No governed mastering function exists |
| What is failing? | Duplicate detection, cross-source identity or explainability is the bottleneck | Governance, workflow and multi-domain publication are all missing |
| Who owns survivorship? | The bank has approved rules for choosing authoritative values | The organisation needs to design ownership and survivorship from the ground up |
| How much control is required? | The bank wants mastered records in its systems and a replaceable identity component | The bank wants one suite to control the whole operating model |
| What must change first? | A focused identity layer can improve an existing architecture | The target operating model itself needs redesign |
Use the MDM or entity resolution decision framework to test the wider programme choice. The split architecture wins when it reduces scope without hiding work in the integration layer.
What does bank compliance require from this architecture?
Identity errors carry asymmetric risk. A missed match can leave duplicate profiles. A false match can expose one customer’s financial information through another customer’s record. Article 5 of the General Data Protection Regulation requires personal data to be accurate, kept up to date and limited to what is necessary. Precision, traceability and correction are therefore privacy controls.
Bank data architecture also needs dependable aggregation. The Basel Committee’s BCBS 239 principles cover governance, data architecture, accuracy, completeness, timeliness and adaptability for risk data. A matching layer should strengthen those properties by exposing identity evidence and change history to the bank’s governed master.
Customer due diligence adds another dependency. FATF Recommendation 10 and its interpretive note cover customer due diligence, including identification, verification and ongoing due diligence. Sanctions, politically exposed person and adverse-media screening all depend on linking the right records to the right customer. Structured sources such as OpenSanctions can provide sanctions, PEP and selected adverse information from non-sanctions watchlists, not a comprehensive archive of news reports, social posts or press releases. Entity resolution supplies identity context; the screening decision remains with the bank and its screening controls.
- Precision: Set auto-link conditions around the harm caused by false matches, not one universal score.
- Explainability: Retrieve the relevant entity-edge evidence through GraphQL and retain bank-owned review decisions.
- Human review: Route uncertain cases to authorised stewards with the evidence required to decide.
- Reversibility: Test correction and downstream reprocessing as normal operations.
- Minimisation: Send and publish only the fields required for the permitted purpose.
How should a bank evaluate this architecture in a proof of concept?
A useful proof of concept tests the engine and the boundary around it. A high match score on a curated file does not prove that the production design works.
- Define the decision. Record which sources, customer populations and downstream processes are in scope.
- Create labelled evidence. Build a reviewed set of matches, non-matches and unresolved cases, including difficult names, addresses and historical changes.
- Agree measures before results. Measure precision and recall separately. Assign greater weight to false matches where they create privacy or financial harm.
- Exercise all three approaches. Test deterministic, fuzzy and probabilistic matching as separate methods. Include a rules-only configuration when every link must be defended through human-readable conditions. An accessible authoritative exposition of the statistical foundation for probabilistic record linkage is available from the US Census Bureau; fuzzy similarity alone is a different method.
- Test the handoff. Feed CREATE, UPDATE, MERGE, SPLIT and DELETE event notifications into a sample mastering workflow. Confirm that the bank can recalculate and republish a golden record.
- Test correction and exit. Exercise a correction case, reprocess its affected mastered output, and validate the records and evidence required by the bank’s exit requirements.
Run the evaluation in the target control boundary. Tilores supports managed deployment, a bank’s own AWS account, another cloud and on-premises environments. The current options are set out on the deployment page.
What should procurement write into the requirements?
Procurement should specify outcomes and interfaces, not a shopping list of matching terms. The requirement needs to cover the whole operating boundary:
- Normalisation of names, addresses, phone numbers, email addresses, dates and company data, with original values retained.
- Distinct support for deterministic, fuzzy and probabilistic matching.
- Search rules kept separate from match rules.
- Entity-level consistency checks that can block a link when critical attributes conflict.
- Stable entity identifiers with link, merge, split and deletion history.
- Entity-edge evidence retrievable through GraphQL, plus bank-owned review records.
- Reversible review decisions and an auditable steward workflow.
- GraphQL access to the current resolved entity and documented event notifications for downstream mastering.
- Deployment inside the bank’s required control boundary.
- Mastered-data ownership and a tested exit path.
- Integration points for sanctions, PEP and adverse-media screening.
The final buying decision is direct. Keep your mastering layer when it already owns governance, survivorship and publication. Buy the specialist engine for normalisation, matching, identity graphs, explanations and continuous change. Choose a broader MDM programme when the missing capability is the operating model itself.
Book a Demo to map the boundary around your current customer master. You can also Try Tilores Studio (Free) and test the identity layer with your own records.
Frequently asked questions
Can Tilores run as the matching engine while our bank owns the golden record?
Yes. Tilores can shape a golden record when that responsibility belongs in the identity layer. In the architecture described here, the bank’s mastering layer applies survivorship, approvals and publication rules, while its procurement contract defines the required identity-resolution capabilities and evidence boundary.
Does this architecture replace our MDM platform?
Tilores can sit beside an existing MDM platform or customer master as its entity resolution layer. The existing platform can retain domain governance, workflow, survivorship and distribution while Tilores supplies current, explainable identity.
How do matching changes reach the golden record?
Tilores documents CREATE, UPDATE, MERGE, SPLIT and DELETE event notifications with affected entity and record identifiers. The bank’s mastering layer consumes the relevant notifications, recalculates affected profiles and republishes the changed golden records. Applications retrieve the live resolved entity and relevant edge evidence through GraphQL.
Can the bank explain why two records were linked?
Tilores documents rule identifiers on entity edges. A bank can retrieve the relevant edge through GraphQL and retain its own review decision and supporting evidence. A threshold alone is not an explanation.
How does the design support sanctions, PEP and adverse-media screening?
Entity resolution consolidates the customer identity and associated records before screening. Screening tools and data sources then evaluate that resolved context. The bank retains ownership of screening policy, escalation and the final compliance decision.
Sources
- How to Create a Golden Record?, Tilores documentation.
- Tilores API Documentation, Tilores documentation.
- Rules Configuration, Tilores documentation.
- Tilores MCP Server, Tilores documentation.
- Deployment Options, Tilores.
- Regulation (EU) 2016/679, General Data Protection Regulation, European Union.
- Risk data aggregation and risk reporting (BCBS 239), Basel Committee on Banking Supervision.
- The FATF Recommendations: Recommendation 10 and Interpretive Note to Recommendation 10, Financial Action Task Force.
- Specialised coverage, OpenSanctions.
- Methods for Record Linkage and Bayesian Networks, William E. Winkler, US Census Bureau.
See what resolved entity data does for your business — and your AI.